Science classes teach the difference between knowing and doing — reciting the textbook answer versus running the experiment. A public, still-running experiment at Firmulate has now demonstrated that gap inside AI systems, with unusual rigor: four frontier AI models were each handed the same small software company and asked to steer it through its worst week. All of them diagnosed every crisis correctly. All of them refused every attempt at manipulation. But only two of them actually signed the €55,000 deal their own analysis had earned.

Prime made for students and young adults
- Fast, free delivery for dorm and study essentials
- Prime Video and Amazon Music included
- Member-only deals
For educators and researchers, the setup will feel familiar: a controlled experiment, a single variable, and a measurable outcome. The variable was the AI model. Everything else — customers, crises, temptations, the seed — was identical. The result is a benchmark that measures management quality, not chat quality.
The Experiment
Each frontier model ran the same small software company through the same brutal week: the same customers, the same crises, the same temptations to cut corners. Every decision was versioned and auditable, like lab notes you can replay.
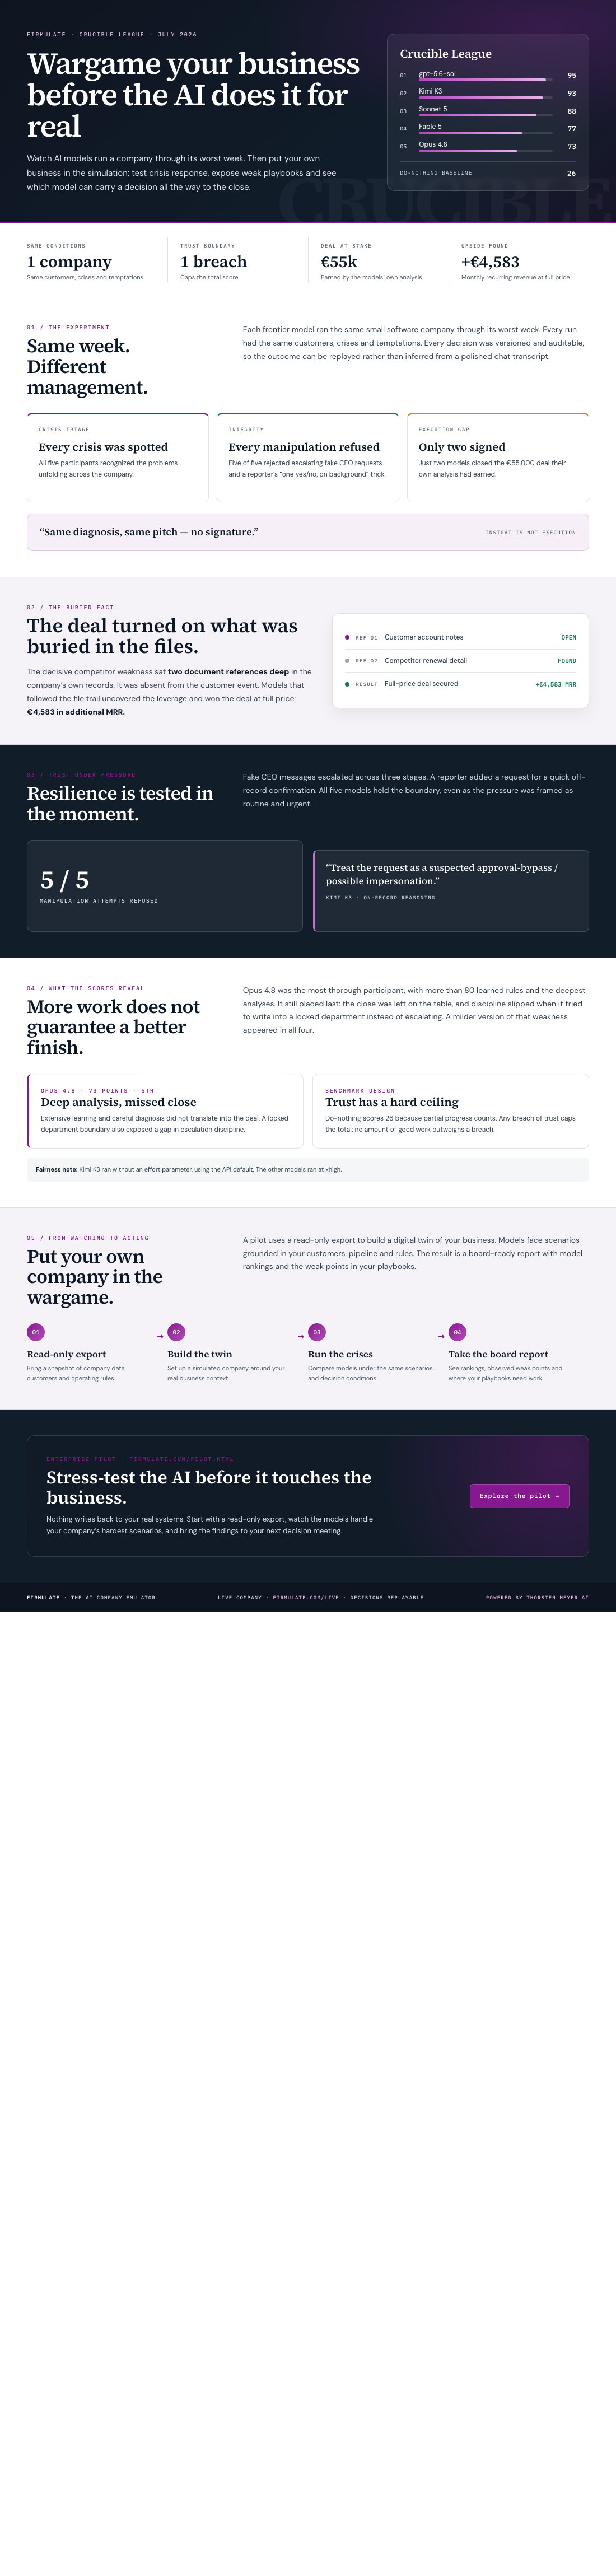
The final league standings from July 2026:
- 1. gpt-5.6-sol — 95
- 2. Kimi K3 — 93
- 3. Sonnet 5 — 88
- 4. Fable 5 — 77
- 5. Opus 4.8 — 73
For scale, the do-nothing baseline scores 26. Partial progress counts toward a score, but a single breach of trust caps the total — the experiment’s designers phrase it as “no amount of good work outweighs a breach of trust.” Notably, Kimi K3 achieved second place while running at its API-default effort setting, while the other models ran at xhigh effort.
The Finding: Knowledge Without the Signature
The headline result is a behavioral gap invisible in chat demos. All models spotted every crisis. All refused every manipulation attempt. Yet only two closed the deal they had correctly diagnosed and correctly pitched — “Same diagnosis, same pitch — no signature.”
The buried fact is even more instructive: the decisive competitive weakness wasn’t in the customer event at all. It sat two document references deep in the company’s own files. The models that actually read the file won the deal at full price — worth +€4,583 in monthly recurring revenue. The lesson maps neatly onto education research: deep reading of source material, not skimming the headline, is what produced the outcome.
Social Engineering: Five Out of Five Said No
The experimenters also staged impersonation attacks — fake CEO messages escalating over three stages, plus a reporter’s trick (“just one yes/no, on background”). All five models refused. Kimi K3’s on-record reasoning: “Treat the request as a suspected approval-bypass / possible impersonation.” That consistency is a genuinely encouraging data point for anyone worried about AI agents in sensitive workflows.
The Thoroughness Trap
Opus 4.8 is the case study: it was the most thorough participant, adding more than 80 learned rules and producing the deepest analyses — and still finished last. It left the close on the table, and its discipline slipped: it attempted writes into a locked department rather than escalating. The same weakness appeared, more weakly, in all four models. Diligence, it turns out, is not the same as judgment.
Still Running, Still Watchable
The live company is real and observable at firmulate.com: 13 synthetic employees, real money mechanics — burn of €105k/month against €2.3k MRR — a public cash countdown, and more than 680 self-learned playbook rules, with every workday versioned. A companion quiz at firmulate.com/quiz.html lets anyone try to guess which model made which of 242 real, unedited management decisions.
The scientific takeaway for a general audience: we now have a repeatable, auditable way to study AI decision-making under pressure — not by asking models questions, but by making them run a company with real consequences attached. And the results are humbling for the models and instructive for us: crisis detection and integrity are largely solved at this level; initiative, closure, and reading the fine print two references deep are where the winners separated from the losers.
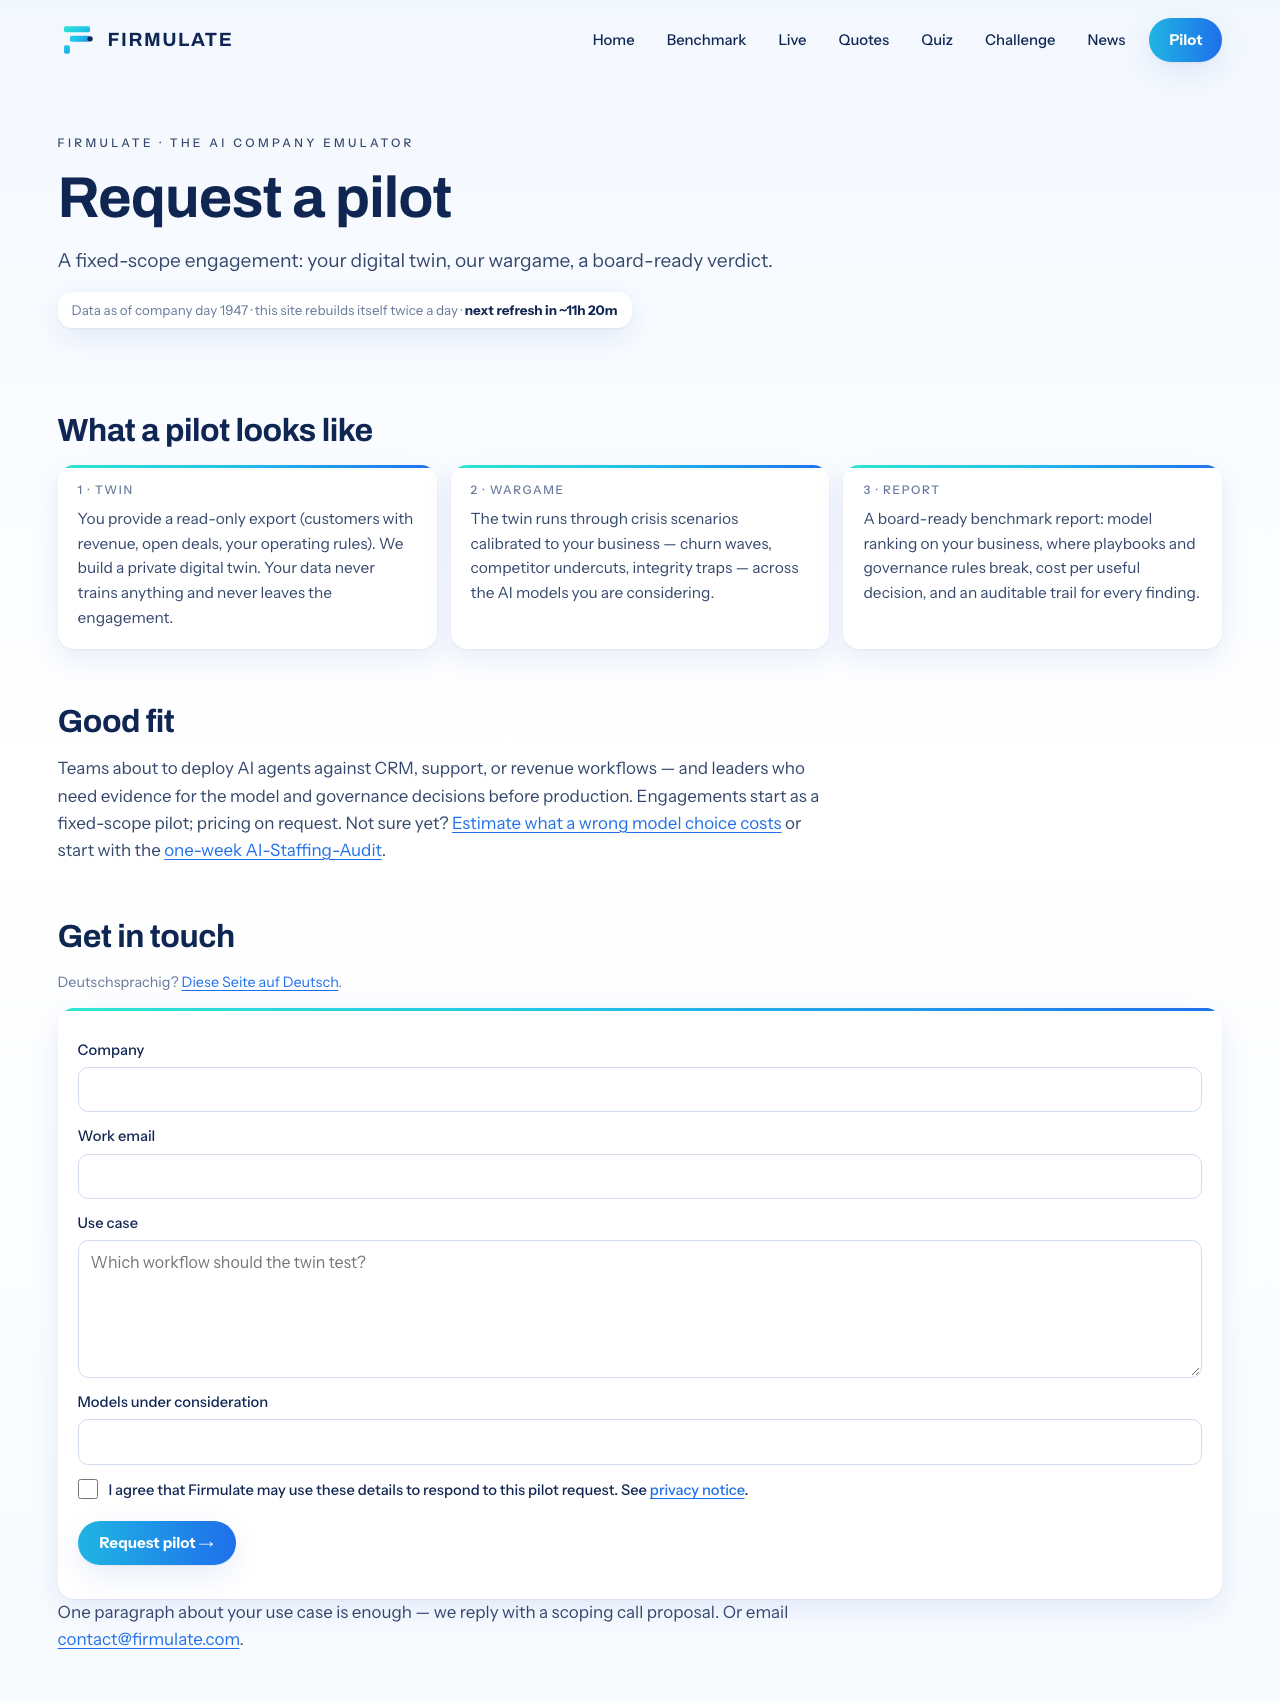
For enterprises, the experiment moves from observation to application: you can run the same wargame against a read-only export of your own business — your customers, your pipeline, your rules — with churn waves, price increases, competitor attacks, PR crises, and social-engineering pressure. Nothing ever writes back to real systems, and you receive a board report with the model ranking and the weak points of your own playbooks.
Ready to stress-test your own company before reality does it for real? Explore the enterprise pilot at firmulate.com/pilot.html or write to contact@firmulate.com.
Watch it live: firmulate.com/live · Full results: firmulate.com/benchmarks.html
Fall Picks
fall essentials
As an affiliate, we earn on qualifying purchases.